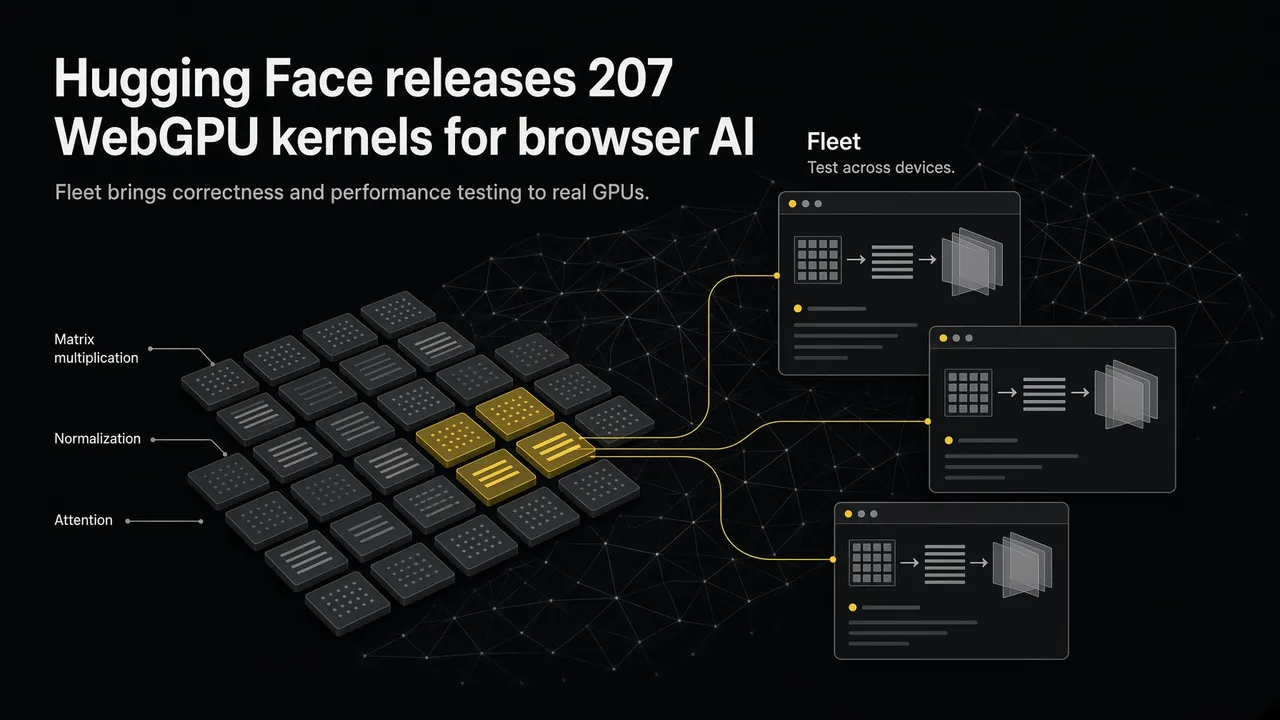
Hugging Face has released (opens in a new tab) an initial collection of 207 open-source WebGPU kernels for local AI workloads, accompanied by a JavaScript library that downloads and runs them directly from the Hugging Face Hub. Announced by Nico Martin (opens in a new tab) and Joshua Lochner (opens in a new tab), the collection covers the low-level operations that browser inference runtimes repeatedly need: matrix multiplication, normalization, convolution, attention primitives, quantization, broadcasting and tensor layout transformations. Everything is Apache 2.0 licensed. This is foundational work rather than another model demo. Faster browser inference ultimately depends on faster individual operations, and WebGPU portability alone does not guarantee good performance across every device.
More than a folder of shaders
Each operation is published as an individual repository within Hugging Face’s WebGPU kernel collection. The repository contains a manifest describing the operation’s contract, metadata and provenance, correctness tests, benchmark cases and parameterized WGSL templates. Theai.onnx.Add kernel, for example, implements element-wise addition with multidirectional broadcasting. It includes separate paths for equal-shaped tensors, vectorized broadcasting, scalar processing and general broadcasting. Applications can load these implementations through the preview version of the @huggingface/kernels npm package: npm install @huggingface/kernels@preview.
Faster on an Apple M4, with caveats
Hugging Face compared its kernels against ORT WebGPU on an Apple M4 GPU using a development version of ONNX Runtime Web 1.30.0. The evaluation started with 1,756 cases across all 207 operations. Hugging Face’s published aggregate covers the 809 cases where both systems produced matching outputs and reliable timings. Across those cases, the company reports a 2.57x geometric-mean speedup and a 1.90x median speedup, with 629 wins, 176 losses and four ties. Familiar operations showed more moderate improvements: Add reached 3.52x, Softmax 2.11x, LayerNormalization 2.22x and MatMul 1.14x. Some specialized workloads produced extreme results. A bilinearEinsum case ran more than 10,000 times faster, while a row-wise CumSum reported a 301x improvement.Fleet takes testing beyond one GPU
Hugging Face has also launched Fleet, a browser-based testing tool that runs correctness and performance trials on the visitor’s GPU. With consent, results contribute private evidence that can expose device-specific failures and slow paths.That broader testing surface may be as valuable as the kernels themselves. WGSL that performs well on an Apple M4 might need different workgroup sizes, vectorization or memory-access patterns on Intel, NVIDIA or mobile hardware. The larger contribution is the packaging model: inspectable WGSL, explicit contracts, correctness fixtures and benchmark cases that travel together.
Browser inference runtimes gain a reusable foundation, while developers get 207 reference implementations they can inspect, measure and improve.
Source: https://huggingface.co/blog/webgpu-kernels (opens in a new tab)